Best AI Video Models (2026)
Compare and run the best AI video generation models in one place. Generate in your browser or over a simple API — pay per run, credits refunded on failed runs.
113 models
Dubbing
ElevenLabs DubbingElevenLabs Dubbing automatically translates and dubs video/audio content into different languages while preserving the original speakers' voices.
1/sec
Video edit
Flux 3 Video EditFLUX 3 Video Edit applies prompt-guided changes to existing videos while preserving motion, timing, and framing, supporting precise video modification, visual style updates, scene refinements, creative edits, ads, and production workflows.
3/sec
Extend a video
Flux 3 Video ExtendFLUX 3 Video Extend continues input videos into new 5-20 second clips, using prompt guidance to control the next action, camera movement, visual style, motion continuity, and optional synchronized audio at 720P / 1080P output.
from205
Image to video
Flux 3 Video Image to VideoFLUX 3 Image-to-Video animates a required reference image into a 5-20 second video, preserving subject appearance while using prompt control to guide motion, camera movement, visual style, and optional synchronized audio at 720P / 1080P output.
from85
Start and end frame
Flux 3 Video Start and End FrameFLUX 3 Start-End-to-Video generates 5-20 second transition videos between required start and end images, using prompt guidance to control action, camera movement, visual style, motion continuity, and optional synchronized audio at 720P / 1080P output.
from85
Text to video
Flux 3 Video Text to VideoFLUX 3 Text-to-Video generates cinematic 5-20 second videos from text prompts, with coherent motion, cinematic composition, optional synchronized audio, and 720P / 1080P output for creative videos, social content, ads, and production workflows.
from85
Image to video
Gemini Omni 1.1 Flash Image to VideoGemini Omni 1.1 Flash Image-to-Video animates a start image into short AI videos, optionally targeting an end frame and generating synchronized audio at resolutions from 360P to 4K for social content, creative storytelling, marketing videos, and production workflows.
from9
Reference to video
Gemini Omni 1.1 Flash Reference to VideoGemini Omni 1.1 Flash Reference-to-Video creates short AI videos with synchronized audio from a text prompt plus optional image and video references, supporting resolutions from 360P to 4K for character-consistent clips, visual reference guidance, social content, marketing videos, and production workflows.
from9
Text to video
Gemini Omni 1.1 Flash Text to VideoGemini Omni 1.1 Flash Text-to-Video creates short AI videos with synchronized audio from text prompts, supporting resolutions from 360P to 4K for social content, creative storytelling, marketing videos, and production workflows.
from9
Video edit
Gemini Omni 1.1 Flash Video EditGemini Omni 1.1 Flash Video Edit applies natural-language edits to existing videos, supporting output resolutions from 360P to 4K for prompt-guided video modification, scene refinements, creative edits, marketing content, and production workflows.
6/sec
Reference to video
Grok Imagine Video 1.5 Reference to VideoxAI Grok Imagine Video v1.5 Reference to Video turns up to seven reference images and a natural-language prompt into short, stylized AI videos, with 480P / 720P output options and selectable aspect ratios for identity-consistent clips, character-driven videos, social media content, creative storytelling, and marketing workflows.
from9
Text to video
Grok Imagine Video 1.5 Text to VideoxAI Grok Imagine Video v1.5 Text to Video turns natural-language prompts into short, stylized AI videos, with 480P, 720P, and 1080P output options plus selectable aspect ratios for social media clips, creative storytelling, concept videos, marketing content, and professional text-to-video workflows.
from8
Dubbing
HeyGen Video TranslateHeyGen Video Translate: AI video translation into 70+ languages and 175+ dialects with no voice actors or dubbing. Fast, accurate.
4/sec
Image to video
Kandinsky 6 Pro Image to VideoKandinsky 6.0 Pro turns a start frame into a high-resolution, cinematic video clip with controllable motion and strong visual fidelity.
from140
Text to video
Kandinsky 6 Pro Text to VideoKandinsky 6.0 Pro is Kandinsky Lab's flagship text-to-video model, generating high-resolution clips with cinematic motion and precise prompt adherence.
from135
Video edit
Kling O3 4K Video EditKling O3 Omni 4K Video Edit edits input videos in 4K with natural-language instructions and optional image references, supporting prompt-guided video modification, visual style updates, scene refinements, motion control, and high-quality cinematic editing.
46.2/sec
Video reference
Kling O3 4K Video ReferenceKling O3 Omni 4K Video Reference generates 4K AI videos guided by an input video, text prompt, and optional reference images, supporting video-to-video creation with visual reference guidance, motion consistency, camera control, and high-quality cinematic output.
from139
Image to video
LTX 2.5 Image to VideoLTX 2.5 Image-to-Video animates a first-frame image into high-fidelity synchronized audio-video content, with optional last-frame guidance and 720P / 1080P / 2K / 4K output for cinematic videos, social content, ads, and production workflows.
from50
Text to video
LTX 2.5 Text to VideoLTX 2.5 Text-to-Video generates high-fidelity synchronized audio-video content from text prompts, with flexible duration and 720P / 1080P / 2K / 4K output for cinematic videos, social content, ads, and production workflows.
from50
Image to video
H3 Image to VideoH3 Open Weights Image to Video animates a first-frame image, optionally with last-frame guidance, into coherent 480P / 540P / 768P videos with native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing.
from12
Camera moves
H3 Max Camera ControlsH3 Max Multi Angle turns a single image into a video with precise, keyframe-based control over the camera's orbit, elevation, and distance in 3D space
5/sec
Image to video
H3 Max Image to Video's H3 Max is a post-trained variant of H3, tuned for stronger prompt adherence and better aesthetics while co-optimized with our custom inference stack for higher throughput with no compromises on output quality
5/sec
Talking avatar
H3 Max Lip-SyncH3 Max Lip Sync generates a video from an image and supplied audio, synchronizing mouth movements to the soundtrack. It supports optional transcription guidance and output resolutions from 480p to 2K.
6/sec
Text to video
H3 Max Text to Video's H3 Max is a post-trained variant of H3, tuned for stronger prompt adherence and better aesthetics while co-optimized with our custom inference stack for higher throughput with no compromises on output quality
5/sec
Image to video
H3 Max Turbo Image to Video's H3 Max Turbo is a post-trained variant of H3, tuned for stronger prompt adherence and better aesthetics while co-optimized with our custom inference stack for higher throughput with no compromises on output quality
2.5/sec
Text to video
H3 Max Turbo Text to Video's H3 Max Turbo is a post-trained variant of H3, tuned for stronger prompt adherence and better aesthetics while co-optimized with our custom inference stack for higher throughput with no compromises on output quality
2.5/sec
Reference to video
H3 Reference to VideoH3 Open Weights Reference to Video generates coherent 480P / 540P / 768P videos from prompts and multimodal references, guided by up to 9 reference images, 3 reference videos, and 3 reference audios, with native stereo audio and flexible reference-based video generation.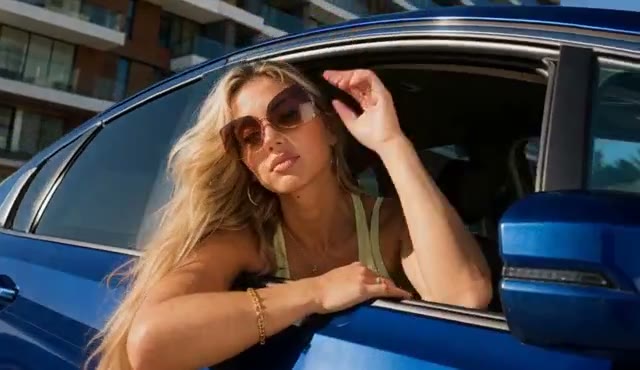
from15
Image to video
H3 Singularity Image to VideoH3 Singularity Open Weights Image-to-Video animates a first-frame image, with optional last-frame guidance, into coherent 480P / 540P / 768P videos with native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing.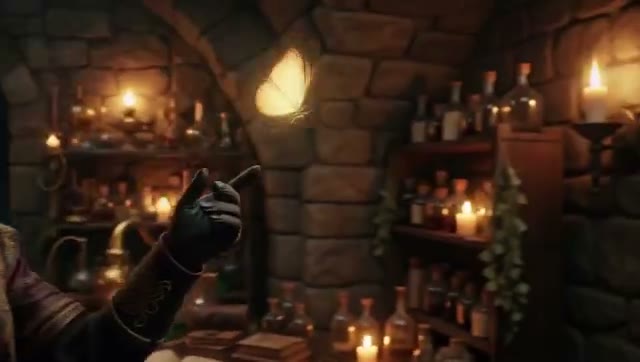
from15
Reference to video
H3 Singularity Reference to VideoH3 Singularity Open Weights Reference to Video generates coherent 480P / 540P / 768P videos from prompts and multimodal references, guided by up to 9 reference images, 3 reference videos, and 3 reference audios, with native stereo audio and flexible reference-based video generation.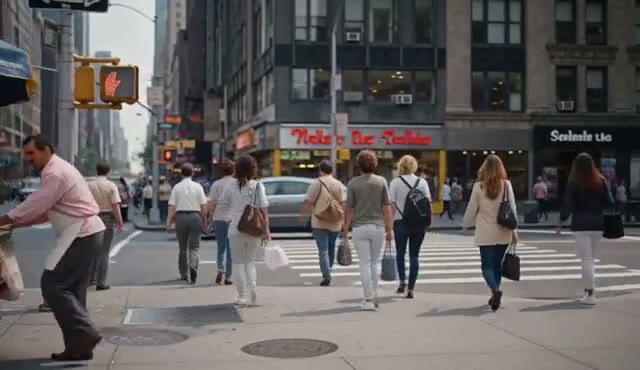
from15
Text to video
H3 Text to VideoH3 Open Weights Text to Video generates coherent videos from text prompts, with 480P / 540P / 768P output, native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing.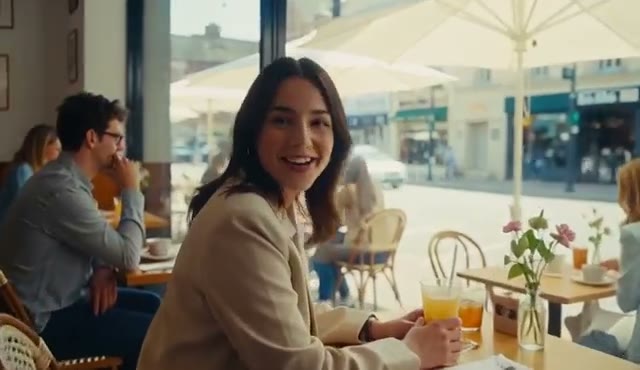
from12
Video edit
H3 Video EditH3 Open Weights Video-Edit edits an input video from a natural-language prompt. The input video drives subject identity, composition, and motion while the model rewrites lighting, style, weather, environment, or specific elements as instructed, with native stereo audio generated in the same pass.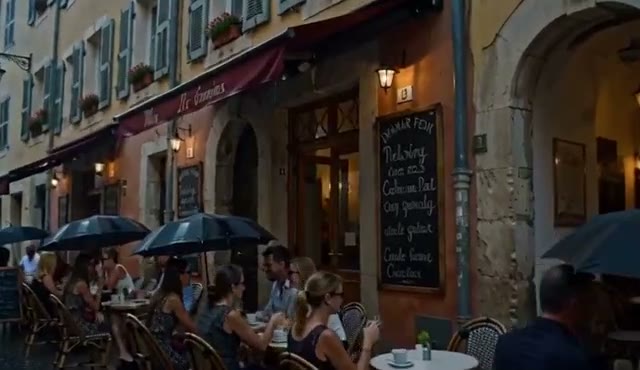
10/sec
Extend a video
H3 Video ExtendH3 Open Weights Video-Extend appends a new cinematic continuation to an existing video. A fresh segment with native stereo audio is generated from the input video's last frame and a natural-language prompt, then the original and new segment are concatenated into a single output.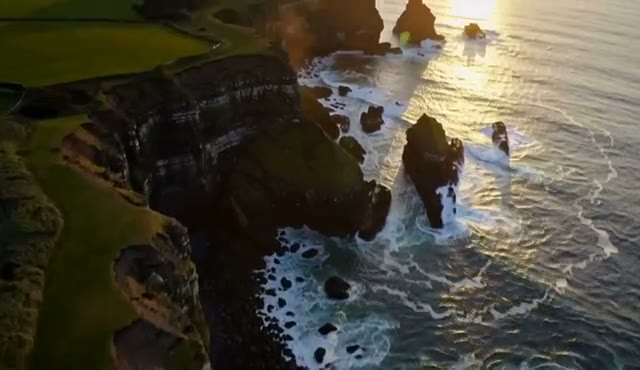
from12
Character swap
MoCha Character SwapSwap the character in a video for someone else. Give it the clip and a reference image, and it replaces the performer while keeping the original motion, timing and audio.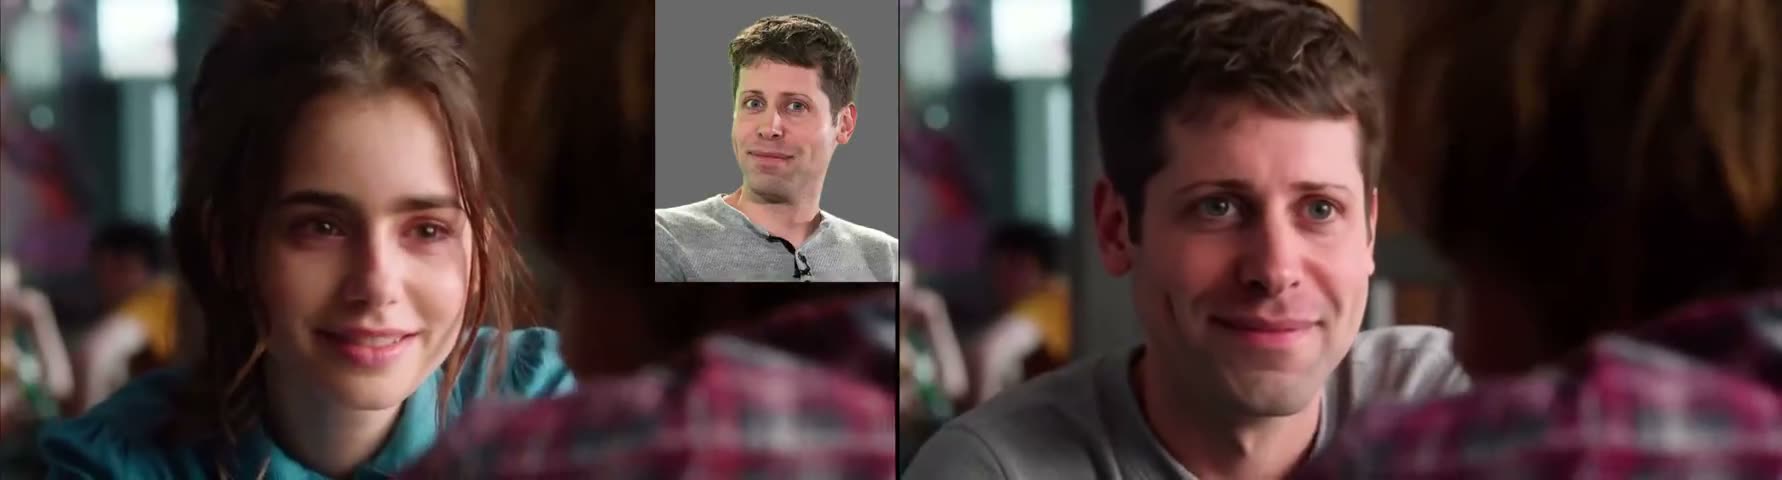
4/sec
Image to video
P-Video 2 Pro Image to VideoP-Video-2-Pro Image-to-Video generates videos from input images with optional last-frame guidance, 480P / 768P output, generated audio, and explicit controls for duration, resolution, and draft mode.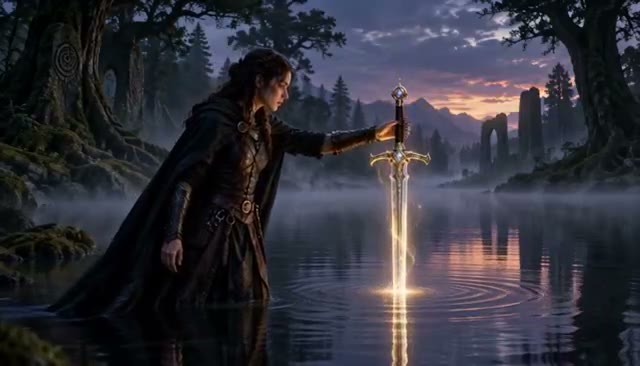
1/sec
Text to video
P-Video 2 Pro Text to VideoP-Video-2-Pro Text-to-Video generates videos from text prompts at 480P / 768P output with generated audio, supporting prompt-driven video creation for creative clips, social content, ads, and production workflows.
1/sec
Character swap
P-Video ReplaceReplace or insert a subject into an existing video. Give it the clip and up to three reference images of who should appear, and it preserves the original motion, timing and audio.
3/sec
Seamless loop
Pixelcut Looping VideoTurn one product photo into a seamless 5 to 15 second video loop with a locked camera, subtle ambient motion or a full 360° spin.
8/sec
Image to video
Realtime Video (Image to Video)Animate a still image into video in seconds rather than minutes. Fast enough to iterate on.
5/sec
Video edit
Runway Aleph 2Runway Aleph 2 Video Edit is an in-context video editing model for precise prompt-based edits, multi-shot consistency, and optional keyframe guidance, supporting 2-30 second input videos and up to 5 keyframes for controlled video modification workflows.
37/sec
Image to video
Seedance 2.5 Image-to-VideoSeedance 2.5 turns a picture into one continuous video of 4 to 30 seconds, with sound generated in sync, at up to 4K. It keeps the picture's subject and framing and adds natural motion; an end frame can set where the shot lands.
from72
Image to video
Seedance 2.5 Image-to-Video TurboSeedance 2.5 Turbo turns a picture into one continuous video of 4 to 30 seconds at 720p or 1080p, with sound generated in sync. Faster and cheaper than Seedance 2.5; an end frame can set where the shot lands.
from80
Text to video
Seedance 2.5 Text-to-VideoSeedance 2.5 makes one continuous video of 4 to 30 seconds from a text prompt, with sound generated in sync, at up to 4K. It follows the prompt closely, takes camera and lighting direction, and keeps motion steady; reference images, videos and audio can guide it.
from72
Text to video
Seedance 2.5 Text-to-Video TurboSeedance 2.5 Turbo makes one continuous video of 4 to 30 seconds from a text prompt at 720p or 1080p, with sound generated in sync. Faster and cheaper than Seedance 2.5, with the same camera and motion control.
from80
Image to video
Vidu Q4 Image to VideoVidu Q4 Image-to-Video animates a single reference image into high-quality AI video with prompt-guided motion, optional audio, 3-16 second duration, and output resolutions from 540P to 4K for product animation, social content, marketing creatives, cinematic visuals, and production workflows.
from14
Reference to video
Vidu Q4 Reference to VideoVidu Q4 Reference-to-Video generates subject-consistent AI videos from text prompts, 1-12 reference images, and up to 3 reference audio clips, supporting character consistency, product videos, social content, brand assets, and reference-guided storytelling workflows.
from14
Video edit
Wan 2.7 Video EditEdit a video by describing the change. Takes up to three reference images to guide who or what appears, and can keep the original audio. Outputs up to 10 seconds.
20/sec
Image to video
Wan 3.0 Image-to-VideoAlibaba WAN 3.0 Image-to-Video converts a first-frame image into a video with optional last-frame guidance, flexible 2-30 second duration, resolution, aspect ratio, audio, and deep-thinking controls.
from10
Image to video
Wan 3.0 Prime Image to VideoWan 3.0 Prime Image to Video is an accelerated variant that animates a first-frame image into a cinematic video, with optional last-frame guidance, flexible 2-30 second duration, aspect ratio control, optional audio, and deep-thinking controls for high-quality motion and scene continuity.
from15
Reference to video
Wan 3.0 Prime Reference to VideoWan 3.0 Prime Reference to Video is an accelerated variant that creates coherent videos from prompts and multimodal references, including images, videos, and audio, with flexible 2-30 second duration and aspect ratio control for subject consistency, motion guidance, timing control, and scene continuity.
from15
Text to video
Wan 3.0 Prime Text to VideoWan 3.0 Prime Text to Video is an accelerated variant that generates cinematic videos from text prompts, with flexible 2-30 second duration, aspect ratio control, optional audio, and deep-thinking controls for high-quality video generation.
from15
Reference to video
Wan 3.0 Reference-to-VideoAlibaba WAN 3.0 Reference-to-Video combines reference images, videos, and audio with prompts to create coherent videos with flexible 2-30 second duration, resolution, aspect ratio, audio, and deep-thinking controls.
from10
Text to video
Wan 3.0 Text-to-VideoAlibaba WAN 3.0 Text-to-Video generates videos from text prompts with flexible 2-30 second duration, resolution, aspect ratio, audio, and deep-thinking controls.
from10
Video edit
Wan 3.0 Video EditWan 3.0 Video Edit edits existing videos with text prompts and optional reference images or audio, supporting prompt-guided scene changes, visual refinements, and multimodal video editing. Inputs longer than 15 seconds are trimmed to the first 15 seconds, with output aspect ratio automatically matched to the input video.
10/sec
Extend a video
Wan 3.0 Video ExtendWan 3.0 Video Extend continues an existing video with a newly generated segment, preserving the source video and its original audio while supporting optional audio generation for the extension. It supports 480P / 720P / 1080P output, optional last-frame guidance, and prompt control for the next action and camera movement.
from10
Text to video
Realtime Video (Text to Video)Describe a shot and get video back in seconds rather than minutes.
5/sec
Talking avatar
InfiniteTalk FastFast lip-sync — animate a portrait to speak any audio in seconds.
1.6/sec
Talking avatar
InfiniteTalkLip-sync any portrait to any audio for a natural talking-avatar video.
3/sec
Image to video
P-Video TurboP-Video — fast, efficient image-to-video generation.
2/sec
Image to video
Seedance V1.5 Pro I2VSeedance 1.5 Pro — high-fidelity image-to-video.
from12
Image to video
Sora 2 I2VSora 2 — turn an image into a coherent, high-quality video.
from40
Image to video
Sora 2 Pro I2VSora 2 Pro — premium image-to-video with longer, sharper results.
from120
Motion control
Kling v2.6 Standard Motion ControlKling 2.6 — animate a subject with motion control for cinematic video.
8.4/sec
Motion control
Kling v3 Motion ControlKling 3.0 motion control: transfer motion from a reference video to any character image with improved consistency and quality.
7/sec
Text to video
Grok Imagine Video EditGenerate videos using xAI's Grok Imagine Video model
from5
Character swap
Wan 2.2 Animate ReplaceUse Wan 2.2 Animate to replace a character in a video scene
2/sec
Image to video
Seedance 2.0 Image-to-VideoSeedance 2 — image-to-video with smooth, dynamic motion.
from48
Text to video
Seedance 2.0 Text-to-VideoSeedance 2 — generate video from a text prompt.
from48
Image to video
Seedance 2.0 Fast Image-to-VideoSeedance 2 Fast — quick image-to-video generation.
from40
Text to video
Seedance 2.0 Fast Text-to-VideoSeedance 2 Fast — quick text-to-video generation.
from40
Text to video
Sora 2 (Text-to-Video)OpenAI Sora 2 is a state-of-the-art text-to-video model with realistic visuals, accurate physics, synchronized audio, and strong steerability.
from40
Text to video
Kling v3 Standard (Text-to-Video)Kling 3.0 Standard delivers high-quality text-to-video generation with smooth motion, cinematic visuals, accurate prompt adherence, and native audio for ready-to-share clips.
from38
Text to video
Seedance V1.5 Pro (Text-to-Video)Seedance 1.5 Pro (Text-to-Video) generates cinematic, live-action–leaning clips from text with strong prompt adherence, expressive motion, and stable aesthetics. It supports 4–12s duration control (including Smart Durati
from10
Text to video
Veo 3.1 Lite (Text-to-Video)Google Veo 3.1 Lite generates high-fidelity videos with native audio from text prompts, optimized for cost efficiency.
from20
Text to video
Veo 3 Fast (Text-to-Video)Google Veo 3 Fast creates text-to-video with synchronized audio, delivering faster, more cost-effective results than standard Veo 3.
from60
Text to video
Hailuo 02 Standard (Text-to-Video)Hailuo 02 is a text-to-video model, fine-tuned to output responsive 768P videos even for complex physics-driven scenes.
from28
Text to video
Wan 2.5 (Text-to-Video)Alibaba WAN 2.5 makes 480p-1080p text/image-to-video with synced audio and is faster, more affordable than Google Veo3.
from25
Text to video
PixVerse V5 (Text-to-Video)PixVerse V5 Text-to-Video generates smooth, natural 5s videos from text prompts in seconds, with 720p output available.
from23
Text to video
P-Video (Text-to-Video)P-Video turns a text prompt into a short video fast and at low cost, good for drafts, social clips and trying many ideas before a final render.
from2
Text to video
LTX-2 Fast (Text-to-Video)LTX-2 Fast is a production-grade text-to-video engine that creates synchronized audio and 1080p video from text prompts.
from24
Text to video
Grok Imagine (Text-to-Video)Generate videos from text descriptions using xAI's Grok Imagine Video model. Create high-quality videos with customizable duration, aspect ratio, and resolution.
from30
Text to video
Wan 2.2 Ultra-Fast 480p (Text-to-Video)Wan 2.2 t2v 480p Ultra-Fast generates unlimited AI videos from text prompts at 480p with ultra-fast inference.
from5
Text to video
Gemini Omni Flash VideoGemini Omni Flash Text-to-Video creates short videos with synchronized audio from a text prompt.
from39
Text to video
Hailuo 2.3Hailuo 2.3 is a text-to-video model creating physics-aware 768p videos with 2.5× efficiency and 85% complex instruction response rate.
from28
Image to video
Hailuo 2.3 (Image to Video)Hailuo 2.3 Standard is an image-to-video model producing physics-aware 768p output with a 2.5x efficiency improvement.
from28
Text to video
Hailuo 2.3 ProHailuo 2.3 Pro is a text-to-video model delivering 1080p videos with 2.5x efficiency and 85% complex-instruction accuracy.
49
Text to video
Kling V3 Turbo ProKling V3 Turbo Pro generates high quality 1080p videos from text prompts, with support for single prompts and multi-shot storyboards.
from42
Image to video
Kling V3 Turbo Pro (Image to Video)Kling V3 Turbo Pro generates high quality 1080p videos from a first-frame image, with optional text prompts and multi-shot storyboards.
from42
Text to video
Kling V3 Turbo StandardKling V3 Turbo Standard generates fast, affordable 720p videos from text prompts, with support for single prompts and multi-shot storyboards.
from34
Image to video
Kling V3 Turbo Standard (Image to Video)Kling V3 Turbo Standard generates fast, affordable 720p videos from a first-frame image, with optional text prompts and multi-shot storyboards.
from34
Text to video
Kling V3.0 ProKling 3.0 Pro delivers top-tier text-to-video generation with smooth motion, cinematic visuals, accurate prompt adherence, and native audio for ready-to-share clips.
from51
Text to video
Kling Video O3 StandardKling Omni Video O3 (Standard) is Kuaishou's advanced unified multi-modal video model with MVL (Multi-modal Visual Language) technology. Text-to-Video mode generates cinematic videos from text prompts with subject consistency, natural physics simulation, and precise semantic understanding. Supports audio generation.
from34
Image to video
Leonardo Motion 2.0Leonardo Motion 2.0 delivers upgraded image-to-video generation, producing more realistic, detailed videos than its predecessor.
30
Text to video
LTX-2 ProLTX-2 Pro is a text-to-video engine that generates synchronized audio and 1080P video from text prompts for production workflows.
from36
Image to video
LTX-2 Pro (Image to Video)LTX-2 is an AI creative engine for production workflows, generating synchronized audio and 1080p video output.
from36
Video edit
Lucy Edit Pro (Video Edit)Lucy Edit Pro is a state-of-the-art video editing model that produces studio-quality results in minutes, not weeks.
10/sec
Text to video
Luma Ray 3.2Luma Ray 3.2 Text-to-Video generates cinematic videos from text prompts with controllable aspect ratio, resolution, duration, and optional reference images.
from50
Image to video
Luma Ray 3.2 (Image to Video)Luma Ray 3.2 Image-to-Video animates a source image into cinematic video guided by a text prompt, with controllable aspect ratio, resolution, duration, and optional reference images.
from50
Text to video
Ovi (Video + Audio)Ovi is a veo-3-like model that converts text or text+image prompts into synchronized video with audio.
15
Text to video
Pika 2.2Pika v2.2 is a text-to-video model that creates high-quality videos from text prompts, supporting multiple video sizes and advanced prompt optimization.
from20
Image to video
Pika 2.2 (Image to Video)Pika V2.2 Image-to-Video converts images into high-quality videos in various sizes with prompt optimization for precise results.
from20
Text to video
Pixverse V6PixVerse V6 generates high-quality videos from text prompts with flexible duration (1-15s), multiple resolutions up to 1080p, and optional audio generation.
from3
Image to video
Pixverse V6 (Image to Video)PixVerse V6 generates high-quality videos from images with flexible duration (1-15s), multiple resolutions up to 1080p, and optional audio generation.
from3
Text to video
Seedance 2.0 MiniSeedance 2.0 Mini is the faster, lower-cost tier of Seedance 2.0 for cinematic multi-shot video — narrative sequences, AI camera control (zoom/pan/tracking), and consistent characters across scenes, from text or image prompts. 480p-4k, 4-15s, aspect ratios 16:9 / 4:3 / 1:1 / 3:4 / 9:16. Priced at 50% of standard Seedance 2.0.
from24
Image to video
Seedance 2.0 Mini (Image to Video)Seedance 2.0 Mini is the faster, lower-cost tier of Seedance 2.0 for cinematic multi-shot video — narrative sequences, AI camera control (zoom/pan/tracking), and consistent characters across scenes, from text or image prompts. 480p-4k, 4-15s, aspect ratios 16:9 / 4:3 / 1:1 / 3:4 / 9:16. Priced at 50% of standard Seedance 2.0.
from24
Image to video
SkyReels V4 (Image to Video)SkyReels V4 Image to Video generates videos from image references and text prompts using the SkyReels V4 image2video workflow.
from33
Text to video
Sora 2 ProOpenAI Sora 2 Pro turns a text prompt into cinematic video with realistic motion, accurate physics and synchronized sound, at higher resolution and finer detail than Sora 2.
from120
Text to video
Veo 3.1Google Veo 3.1 converts text prompts into videos with synchronized audio at native 1080p for high-quality outputs.
from160
Image to video
Veo 3.1 (Image to Video)Google Veo 3.1 is an Image-to-Video model that converts images into high-quality videos with native 1080P output for enhanced detail and creative flexibility.
from160
Text to video
Veo 3.1 FastGoogle Veo 3.1 Fast creates text-to-video with native 1080p and synchronized audio, delivering high-quality videos for creators.
from60
Image to video
Veo 3.1 Fast (Image to Video)Google Veo 3.1 Fast is an Image-to-Video model with native 1080p output for high-detail videos from images and fast performance.
from60
Text to video
Wan 2.7Alibaba WAN 2.7 Text-to-Video turns plain prompts into coherent, cinematic clips with crisp detail, stable motion, and strong instruction-following—great for ads, explainers, and social posts.
from20
Image to video
Wan 2.7 (Image to Video)Alibaba WAN 2.7 converts images into videos (720p/1080p) with optional audio, supporting first and last frame control.
from20
Image to video
Wan 2.7 Pro (Image to Video)Alibaba WAN 2.7 Pro converts images into ultra-high-resolution videos (1080p/2K/4K) with cinematic detail and smooth motion.
from70
Frequently asked
What is the best AI video model in 2026?
It depends on your goal: Sora and Veo lead on cinematic realism, Kling on motion control, and Seedance and PixVerse on speed and cost. Every model below runs in the same playground, so you can compare them side by side on your own prompt.
Can I use these AI video models via API?
Yes — every model is callable over a simple REST API with a single key, billed per run in credits. See the developer docs to get started.
How much does AI video generation cost?
Each model shows its exact per-run credit cost before you run it. Cheaper models start in the single digits of credits per clip; premium cinematic models cost more. Failed runs are refunded automatically.