Run the best AI models in one playground
Generate images, video, and voice with top image, video and speech models — try any model live in your browser, or call it programmatically over a simple API. No setup, credits refunded on failed runs.
Text- and image-to-video, motion control, lip-sync and more.
Best video models 2026 →Video models
72 models
ElevenLabs Dubbing
ElevenLabs Dubbing automatically translates and dubs video/audio content into different languages while preserving the original speakers' voices.
HeyGen Video Translate
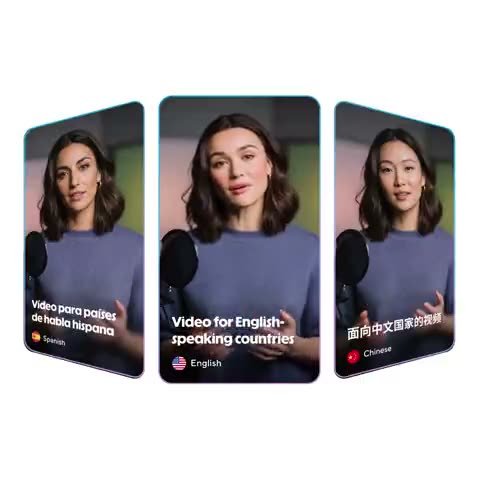
HeyGen Video Translate: AI video translation into 70+ languages and 175+ dialects with no voice actors or dubbing. Fast, accurate.
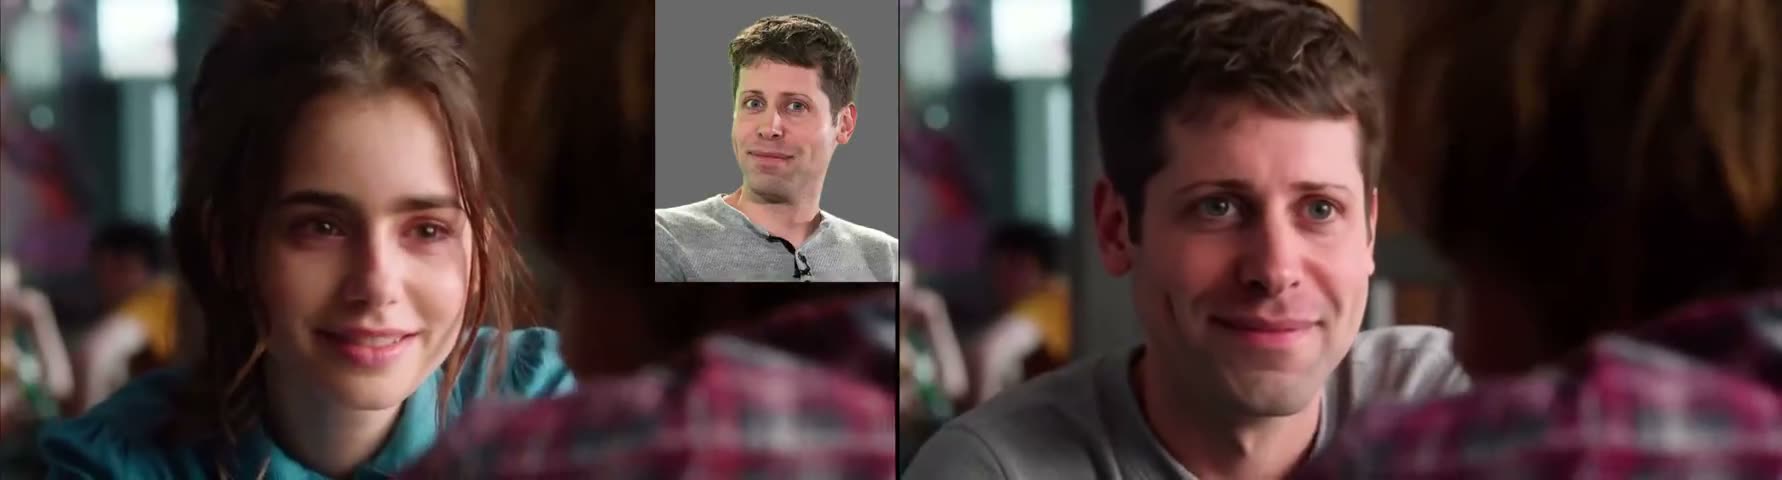
MoCha Character Swap
Swap the character in a video for someone else. Give it the clip and a reference image, and it replaces the performer while keeping the original motion, timing and audio.
P-Video Replace
Replace or insert a subject into an existing video. Give it the clip and up to three reference images of who should appear, and it preserves the original motion, timing and audio.
Realtime Video (Image to Video)
Animate a still image into video in seconds rather than minutes. Fast enough to iterate on.
Seedance 2.5 Image-to-Video
Seedance 2.5 (Image-to-Video) generates Hollywood-grade cinematic videos from reference images and text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it preserves the input image's subject and composition while adding expressive, physically accurate motion.
Seedance 2.5 Image-to-Video Turbo
Seedance 2.5 (Image-to-Video Turbo) generates cinematic 720p/1080p videos from reference images and text prompts —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability. Built on Seed's unified multimodal architecture.
Seedance 2.5 Text-to-Video
Seedance 2.5 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it leads on instruction adherence, motion quality, and visual aesthetics.
Seedance 2.5 Text-to-Video Turbo
Seedance 2.5 (Text-to-Video Turbo) generates cinematic videos from text prompts at 720p and 1080p with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability — optimized for turbo output. Built on Seed's unified multimodal architecture.
Wan 2.7 Video Edit
Edit a video by describing the change. Takes up to three reference images to guide who or what appears, and can keep the original audio. Outputs up to 10 seconds.
Wan 3.0 Image-to-Video
Alibaba WAN 3.0 Image-to-Video converts a first-frame image into a video with optional last-frame guidance, flexible 2-30 second duration, resolution, aspect ratio, audio, and deep-thinking controls.
Wan 3.0 Reference-to-Video
Alibaba WAN 3.0 Reference-to-Video combines reference images, videos, and audio with prompts to create coherent videos with flexible 2-30 second duration, resolution, aspect ratio, audio, and deep-thinking controls.
Wan 3.0 Text-to-Video
Alibaba WAN 3.0 Text-to-Video generates videos from text prompts with flexible 2-30 second duration, resolution, aspect ratio, audio, and deep-thinking controls.
Realtime Video (Text to Video)
Describe a shot and get video back in seconds rather than minutes.
InfiniteTalk Fast
Fast lip-sync — animate a portrait to speak any audio in seconds.
InfiniteTalk
Lip-sync any portrait to any audio for a natural talking-avatar video.
P-Video Turbo
P-Video — fast, efficient image-to-video generation.
Seedance V1.5 Pro I2V
Seedance 1.5 Pro — high-fidelity image-to-video.
Sora 2 I2V
Sora 2 — turn an image into a coherent, high-quality video.
Sora 2 Pro I2V
Sora 2 Pro — premium image-to-video with longer, sharper results.
Kling v2.6 Standard Motion Control
Kling 2.6 — animate a subject with motion control for cinematic video.
Kling v3 Motion Control
Kling 3.0 motion control: transfer motion from a reference video to any character image with improved consistency and quality.
Grok Imagine Video Edit
Generate videos using xAI's Grok Imagine Video model
Wan 2.2 Animate Replace
Use Wan 2.2 Animate to replace a character in a video scene
Seedance 2.0 Image-to-Video
Seedance 2 — image-to-video with smooth, dynamic motion.
Seedance 2.0 Text-to-Video
Seedance 2 — generate video from a text prompt.
Seedance 2.0 Fast Image-to-Video
Seedance 2 Fast — quick image-to-video generation.
Seedance 2.0 Fast Text-to-Video
Seedance 2 Fast — quick text-to-video generation.
Sora 2 (Text-to-Video)
OpenAI Sora 2 is a state-of-the-art text-to-video model with realistic visuals, accurate physics, synchronized audio, and strong steerability.
Kling v3 Standard (Text-to-Video)
Kling 3.0 Standard delivers high-quality text-to-video generation with smooth motion, cinematic visuals, accurate prompt adherence, and native audio for ready-to-share clips.
Seedance V1.5 Pro (Text-to-Video)
Seedance 1.5 Pro (Text-to-Video) generates cinematic, live-action–leaning clips from text with strong prompt adherence, expressive motion, and stable aesthetics. It supports 4–12s duration control (including Smart Durati
Veo 3.1 Lite (Text-to-Video)
Google Veo 3.1 Lite generates high-fidelity videos with native audio from text prompts, optimized for cost efficiency.
Veo 3 Fast (Text-to-Video)
Google Veo 3 Fast creates text-to-video with synchronized audio, delivering faster, more cost-effective results than standard Veo 3.
Hailuo 02 Standard (Text-to-Video)
Hailuo 02 is a text-to-video model, fine-tuned to output responsive 768P videos even for complex physics-driven scenes.
Wan 2.5 (Text-to-Video)
Alibaba WAN 2.5 makes 480p-1080p text/image-to-video with synced audio and is faster, more affordable than Google Veo3.
PixVerse V5 (Text-to-Video)
PixVerse V5 Text-to-Video generates smooth, natural 5s videos from text prompts in seconds, with 720p output available.
P-Video (Text-to-Video)
p-video model running.
LTX-2 Fast (Text-to-Video)
LTX-2 Fast is a production-grade text-to-video engine that creates synchronized audio and 1080p video from text prompts.
Grok Imagine (Text-to-Video)
Generate videos from text descriptions using xAI's Grok Imagine Video model. Create high-quality videos with customizable duration, aspect ratio, and resolution.
Wan 2.2 Ultra-Fast 480p (Text-to-Video)
Wan 2.2 t2v 480p Ultra-Fast generates unlimited AI videos from text prompts at 480p with ultra-fast inference.
Gemini Omni Flash Video
Gemini Omni Flash Text-to-Video creates short videos with synchronized audio from a text prompt.
Hailuo 2.3
Hailuo 2.3 is a text-to-video model creating physics-aware 768p videos with 2.5× efficiency and 85% complex instruction response rate.
Hailuo 2.3 (Image to Video)
Hailuo 2.3 Standard is an image-to-video model producing physics-aware 768p output with a 2.5x efficiency improvement.
Hailuo 2.3 Pro
Hailuo 2.3 Pro is a text-to-video model delivering 1080p videos with 2.5x efficiency and 85% complex-instruction accuracy.
Kling V3 Turbo Pro
Kling V3 Turbo Pro generates high quality 1080p videos from text prompts, with support for single prompts and multi-shot storyboards.
Kling V3 Turbo Pro (Image to Video)
Kling V3 Turbo Pro generates high quality 1080p videos from a first-frame image, with optional text prompts and multi-shot storyboards.
Kling V3 Turbo Standard
Kling V3 Turbo Standard generates fast, affordable 720p videos from text prompts, with support for single prompts and multi-shot storyboards.
Kling V3 Turbo Standard (Image to Video)
Kling V3 Turbo Standard generates fast, affordable 720p videos from a first-frame image, with optional text prompts and multi-shot storyboards.
Kling V3.0 Pro
Kling 3.0 Pro delivers top-tier text-to-video generation with smooth motion, cinematic visuals, accurate prompt adherence, and native audio for ready-to-share clips.
Kling Video O3 Standard
Kling Omni Video O3 (Standard) is Kuaishou's advanced unified multi-modal video model with MVL (Multi-modal Visual Language) technology. Text-to-Video mode generates cinematic videos from text prompts with subject consistency, natural physics simulation, and precise semantic understanding. Supports audio generation.
Leonardo Motion 2.0
Leonardo Motion 2.0 delivers upgraded image-to-video generation, producing more realistic, detailed videos than its predecessor.
LTX-2 Pro
LTX-2 Pro is a text-to-video engine that generates synchronized audio and 1080P video from text prompts for production workflows.
LTX-2 Pro (Image to Video)
LTX-2 is an AI creative engine for production workflows, generating synchronized audio and 1080p video output.
Lucy Edit Pro (Video Edit)
Lucy Edit Pro is a state-of-the-art video editing model that produces studio-quality results in minutes, not weeks.
Luma Ray 3.2
Luma Ray 3.2 Text-to-Video generates cinematic videos from text prompts with controllable aspect ratio, resolution, duration, and optional reference images.
Luma Ray 3.2 (Image to Video)
Luma Ray 3.2 Image-to-Video animates a source image into cinematic video guided by a text prompt, with controllable aspect ratio, resolution, duration, and optional reference images.
Ovi (Video + Audio)
Ovi is a veo-3-like model that converts text or text+image prompts into synchronized video with audio.
Pika 2.2
Pika v2.2 is a text-to-video model that creates high-quality videos from text prompts, supporting multiple video sizes and advanced prompt optimization.
Pika 2.2 (Image to Video)
Pika V2.2 Image-to-Video converts images into high-quality videos in various sizes with prompt optimization for precise results.
Pixverse V6
PixVerse V6 generates high-quality videos from text prompts with flexible duration (1-15s), multiple resolutions up to 1080p, and optional audio generation.
Pixverse V6 (Image to Video)
PixVerse V6 generates high-quality videos from images with flexible duration (1-15s), multiple resolutions up to 1080p, and optional audio generation.
Seedance 2.0 Mini
Seedance 2.0 Mini is the faster, lower-cost tier of Seedance 2.0 for cinematic multi-shot video — narrative sequences, AI camera control (zoom/pan/tracking), and consistent characters across scenes, from text or image prompts. 480p-4k, 4-15s, aspect ratios 16:9 / 4:3 / 1:1 / 3:4 / 9:16. Priced at 50% of standard Seedance 2.0.
Seedance 2.0 Mini (Image to Video)
Seedance 2.0 Mini is the faster, lower-cost tier of Seedance 2.0 for cinematic multi-shot video — narrative sequences, AI camera control (zoom/pan/tracking), and consistent characters across scenes, from text or image prompts. 480p-4k, 4-15s, aspect ratios 16:9 / 4:3 / 1:1 / 3:4 / 9:16. Priced at 50% of standard Seedance 2.0.
SkyReels V4 (Image to Video)
SkyReels V4 Image to Video generates videos from image references and text prompts using the SkyReels V4 image2video workflow.
Sora 2 Pro
openai/sora2
Veo 3.1
Google Veo 3.1 converts text prompts into videos with synchronized audio at native 1080p for high-quality outputs.
Veo 3.1 (Image to Video)
Google Veo 3.1 is an Image-to-Video model that converts images into high-quality videos with native 1080P output for enhanced detail and creative flexibility.
Veo 3.1 Fast
Google Veo 3.1 Fast creates text-to-video with native 1080p and synchronized audio, delivering high-quality videos for creators.
Veo 3.1 Fast (Image to Video)
Google Veo 3.1 Fast is an Image-to-Video model with native 1080p output for high-detail videos from images and fast performance.
Wan 2.7
Alibaba WAN 2.7 Text-to-Video turns plain prompts into coherent, cinematic clips with crisp detail, stable motion, and strong instruction-following—great for ads, explainers, and social posts.
Wan 2.7 (Image to Video)
Alibaba WAN 2.7 converts images into videos (720p/1080p) with optional audio, supporting first and last frame control.
Wan 2.7 Pro (Image to Video)
Alibaba WAN 2.7 Pro converts images into ultra-high-resolution videos (1080p/2K/4K) with cinematic detail and smooth motion.
Generate, edit and restyle images at production quality.
Best image models 2026 →Image models
41 modelsNo preview yet
AI Image Translator
AI Image Translator that extracts text from images and translates it into 30+ languages while perfectly preserving font, style, spacing, and layout. The output image retains the original look and feel with extremely high visual fidelity.
GPT Image 2
OpenAI image generation — excellent prompt-following and clean text rendering; takes reference images.
GPT Image 2.5 Flare
Generates images from a text prompt, with five quality tiers up to 4K and strong in-image typography. Flare is the fast, balanced tier for everyday generation at low latency.
GPT Image 2.5 Flare Edit
Edits up to 16 reference images from natural-language instructions, with five quality tiers up to 4K. Flare is the fast, balanced tier for everyday generation at low latency.
GPT Image 2.5 Sunburst
Generates images from a text prompt, with five quality tiers up to 4K and strong in-image typography. Sunburst is the precision tier — it spends longer per image for extra fidelity on intricate detail.
GPT Image 2.5 Sunburst Edit
Edits up to 16 reference images from natural-language instructions, with five quality tiers up to 4K. Sunburst is the precision tier — it spends longer per image for extra fidelity on intricate detail.
Qwen Image Translate
Alibaba Qwen Vision Translate offers OCR-based image understanding and multilingual in-image text translation for context-aware results.

Z-Image Turbo Img2Img
Image 2 Image version of z-image-turbo with lora support.

Flux Kontext Pro
A state-of-the-art text-based image editing model that delivers high-quality outputs with excellent prompt following and consistent results for transforming images through natural language

Z-Image Turbo
Z-Image Turbo is a super fast text-to-image model of 6B parameters developed by Tongyi-MAI.

Flux Schnell
The fastest image generation model tailored for local development and personal use

Flux 2 Klein 4B
Very fast image generation and editing model. 4 steps distilled, sub-second inference for production and near real-time applications.
Flux 2 Dev
Quality image generation and editing with support for reference images

SeedReam 5 Lite
Seedream 5.0 lite: image generation with built-in reasoning, example-based editing, and deep domain knowledge

Flux Kontext Fast
Ultra fast flux kontext endpoint

Grok Imagine Image
SOTA image model from xAI

Image Head Swap
Swap a face onto any photo while keeping the body, pose and background.

Infinite You
Generate consistent, photorealistic portraits of a person from one reference image.

Nano Banana 2 (Edit Fast)
Blend two photos — keep your subject and apply a reference scene or style.
Nano Banana 2 (Edit)
Edit an image using up to 14 reference images with Google Nano Banana 2.

Bria GenFill (Inpaint)
Bria FIBO Edit GenFill fills masked regions in an image from a text prompt using Bria's licensed-data image editing API.

Gemini 3 Pro Image
Google's Gemini 3.0 Pro (Gemini 3.0 Pro Preview) is a cutting-edge text-to-image model enabling high-res 4K image generation optimized for phones.

Ideogram V3 Quality
Ideogram V3 Quality is the highest-quality Ideogram text-to-image model, producing realistic, creative, and style-consistent images for design and branding.

Ideogram V4
Ideogram V4 generates high-quality images, posters, and logos from text prompts with strong typography, sharp detail, and flexible output sizes. Supports text-to-image and image-to-image (provide an optional source image), 1k / 2k resolution tiers, and low / medium / high quality.

Image 01
Image 01 to generate images from text input..

Imagen 4
Google's Imagen 4 is the flagship text-to-image model for generating images from text prompts with strong fidelity and creative control.

Imagen 4 Ultra
Imagen4 Ultra is Google's highest-quality text-to-image model, generating high-fidelity images from simple text prompts.

Kling Image V3
Kling V3.0 is Kuaishou's latest AI image generation model with superior text-to-image capabilities.

Luma Photon
Luma Photon is a text-to-image model that converts text prompts into images for prompt-based visual generation.

MAI Image 2.5
Microsoft MAI Image 2.5 Text to Image generates photorealistic, design-ready images from text prompts.

Midjourney
Generate high-quality images with Midjourney v8.1 from a text prompt, with optional style reference, aspect ratio, HD mode, and creative controls.

Nano Banana Pro
Google's Nano Banana pro (Gemini 3.0 Pro Image) is a cutting-edge text-to-image model enabling high-res 4K image generation optimized for phones.

NVIDIA ChronoEdit
NVIDIA Chrono Edit is a state-of-the-art image-to-image AI editor that turns photos into stylized edits and retouches with a few clicks.

Qwen Image 2.0
Qwen Image 2.0 text-to-image model with enhanced image quality and improved prompt understanding.

Qwen Image 2.0 Edit
Qwen Image 2.0 edit model with enhanced editing quality and improved instruction understanding.

Recraft V4
Recraft V4 generates high-quality images from text prompts with color palette control.

Recraft V4.1 Pro
Recraft V4.1 Pro Text to Image generates premium high-resolution raster images from text prompts.

Runway Gen-4 Image
RunwayML Gen4 Image model lets you generate precise images using up to 3 reference images to capture every angle and detail.

Seedream 5.0 Lite Edit
Seedream 5.0-lite is a state-of-art image model. Seedream 4.0: Surpassing nano bananain every aspect.

Seedream 5.0 Pro
Seedream 5.0 Pro API Preview is the advanced image generation model for text-to-image and reference-image generation.

Wan 2.7 Image Edit Pro
Alibaba WAN 2.7 Image Edit Pro performs prompt-driven image editing with multi-image reference support and up to 4K output.
Text-to-speech and voice generation you can ship.
Best audio models 2026 →Audio & voice
17 modelsNo preview yet
Gemini TTS
Natural speech with expressive delivery. Supports two speakers in one take.

XTTS-v2
Coqui XTTS-v2: Multilingual Text To Speech Voice Cloning

Chatterbox Turbo
The fastest open source TTS model without sacrificing quality.

Speech-02-HD
Text-to-Audio (T2A) that offers voice synthesis, emotional expression, and multilingual capabilities. Optimized for high-fidelity applications like voiceovers and audiobooks.

Speech-02-Turbo
Text-to-Audio (T2A) that offers voice synthesis, emotional expression, and multilingual capabilities. Designed for real-time applications with low latency
Zonos 2
Voice cloning + text-to-speech — clone a voice from a short sample and make it say anything, multilingual.

ElevenLabs Eleven V3
ElevenLabs eleven-v3 is a text-to-speech model available as a hosted endpoint.

ElevenLabs Multilingual V2
ElevenLabs Multilingual V2 is a multilingual text-to-speech model.

ElevenLabs Music
ElevenLabs Music generates original songs from text descriptions. Create instrumentals or full compositions with customizable duration.

Lyria 3 Pro
Google Lyria 3 Pro generates high-quality music tracks from text prompts and optional image input.

Mirelo SFX 1.6
Mirelo SFX1.6 Text To Audio generates sound effects or ambient audio directly from a text prompt, with optional seamless ambience looping.

Mureka V9 (Song)
mureka ai / mureka v9 / generate song via Mureka official API.

Music 2.6
Music 2.6 generates complete songs with vocals and instrumentals from text prompts and lyrics.

Qwen3 TTS Flash
Alibaba Qwen3 TTS Flash: Low-latency Text-to-Speech for English and Chinese with multiple voices, ideal for real-time dialogue.

Seed Audio 1.0
Seed Audio 1.0 generates natural speech and audio from a prompt, with optional voice, reference audio, or reference image guidance.

Seed Speech TTS 2.0
Seed Speech TTS 2.0 converts text into natural speech with multilingual voices, delivery controls, and MP3 or Opus output.

Speech 2.8 HD
's high-definition text-to-speech model with natural pronunciation and clear articulation.